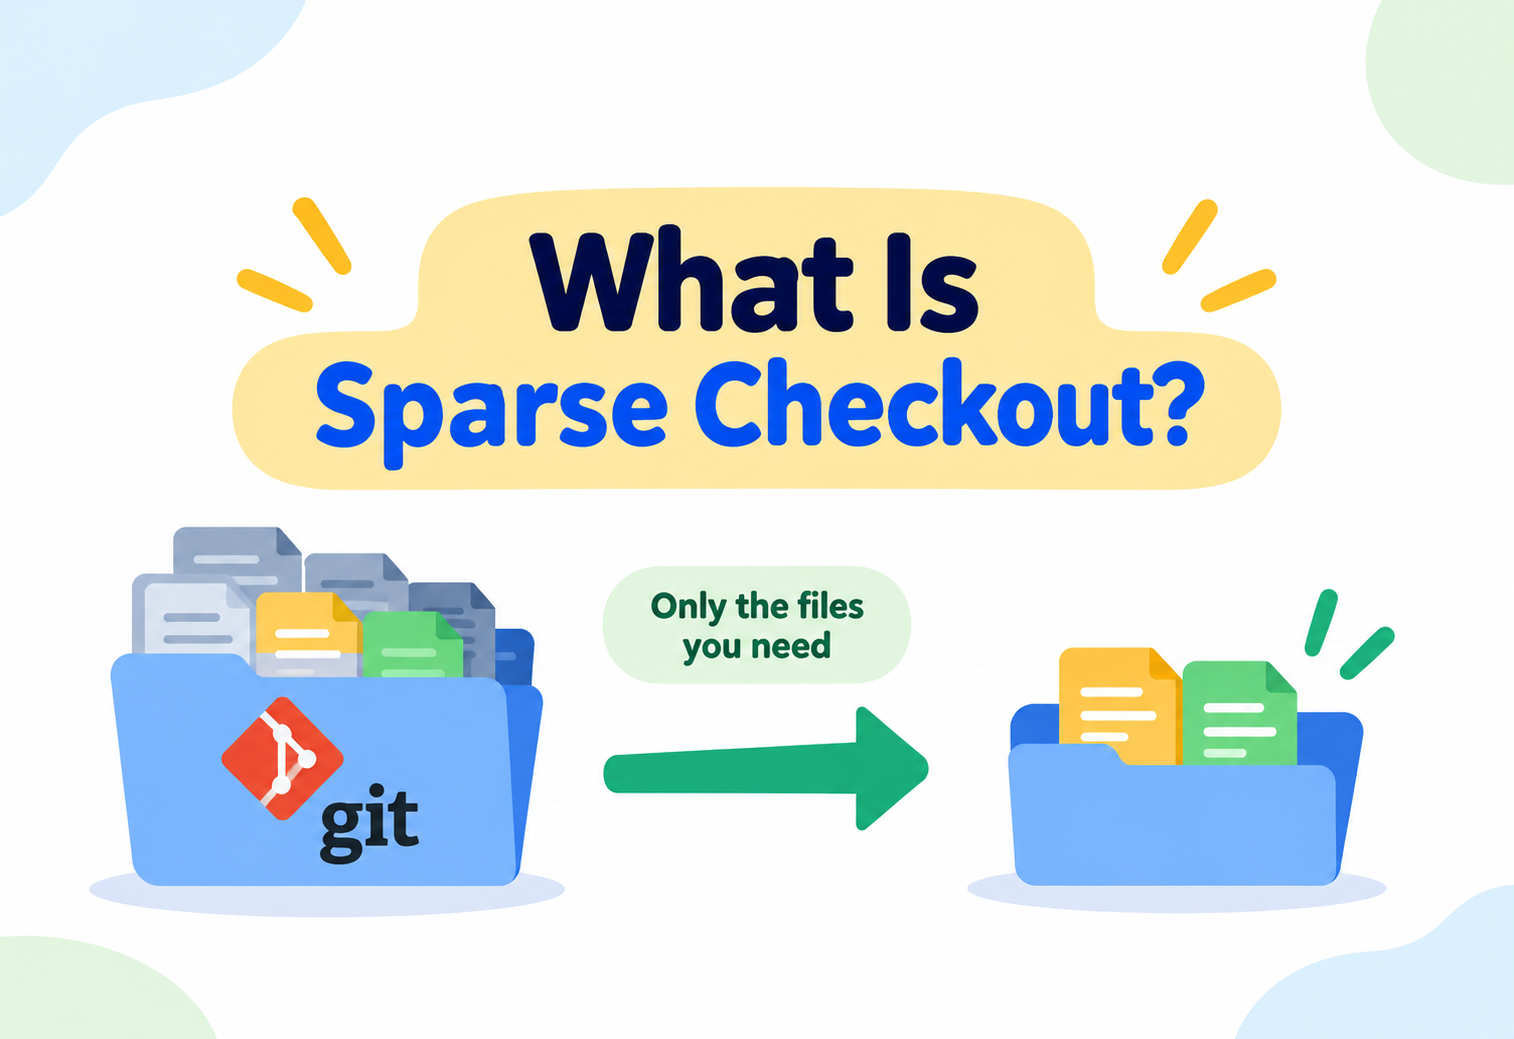
What Is Sparse Checkout?
An advanced, expert-level deep dive into sparse checkout — the Git feature that lets you clone a massive repository's full history while only ever populating your working directory with the specific slice of it you actually need.
Clone a genuinely massive repository — hundreds of thousands of files, a codebase serving dozens of teams — and you inherit every single one of those files on your disk, whether or not your actual work touches even one percent of them. Sparse checkout exists to break that assumption: it lets Git still track and fetch the repository’s full history, while only ever materializing the specific folders you actually care about into your working directory. This guide goes deep into how sparse checkout works internally, how it differs from simply not cloning certain files, and how large engineering organizations use it to keep enormous monorepos practical to work in day to day.
1Core Concept: What Is Sparse Checkout?
Sparse checkout is a Git feature that lets you define a subset of a repository’s directory structure to actually populate in your working directory, while the rest of the repository’s tracked content remains known to Git (present in its object database and history) but simply isn’t written out as files on your disk. It answers a specific, narrow question: “I need Git to know about everything, but I only want to see and work with this particular slice of it.”
Think of a massive, multi-wing university library that has fully catalogued and stored every book it owns, but a specific reading room only physically displays the small selection of books relevant to the course you’re currently taking. The library’s complete catalog — every title, every record — still fully exists and can be searched or retrieved from; the reading room just chooses not to physically stock everything on its shelves, keeping the visible, browsable selection focused and manageable. Sparse checkout works the same way: the full repository is fully known to Git, but your working directory only physically contains the slice you’ve asked for.
Picture a concrete scenario: a company maintains a single enormous monorepo containing the code for forty different internal services, totaling hundreds of thousands of files. A backend engineer named Tomás works exclusively on two of those services. Without sparse checkout, cloning this repository would populate his laptop with every file from every one of the other thirty-eight services he’ll likely never touch — slowing down his editor, his file searches, and his disk usage for no practical benefit. With sparse checkout configured to include only the two services and shared libraries he actually needs, his working directory contains a small, focused fraction of the total repository, while Git still has full, complete access to the entire project’s history and object database underneath.
Sparse checkout controls what’s materialized as files in your working directory. It does not, by itself, reduce what’s fetched or stored in your local object database — that’s a related but distinct concern, covered later in this guide under partial clone. Understanding this separation clearly is the single most important thing for using sparse checkout correctly.
2Why It Exists
Git was originally designed with the assumption that a working directory should mirror the entire tracked repository — a reasonable default for most projects, where the whole codebase is a manageable size. But as organizations increasingly consolidated many services and projects into single, shared monorepos for easier cross-project coordination, that assumption started breaking down badly at scale: a working directory mirroring an entire multi-hundred-thousand-file repository becomes genuinely painful to work with, even when any individual engineer only ever touches a small corner of it.
Sparse checkout exists to decouple “what Git knows about” from “what’s actually sitting on your disk as files,” letting enormous, shared repositories remain practical to work in for individual contributors, without forcing organizations to fragment a genuinely unified codebase into many separate, harder-to-coordinate repositories just to keep individual working directories manageable.
“Why not just split a massive monorepo into many smaller repositories instead of using sparse checkout?” — The expected answer: splitting repositories has real costs too — coordinated cross-project changes become harder, shared tooling and dependency management fragments, and atomic commits spanning multiple projects become impossible. Sparse checkout offers a way to keep the benefits of a single, unified repository while still giving individual engineers a manageable, focused working directory.
3The Monorepo Problem
To appreciate why sparse checkout matters, it’s worth walking through exactly what goes wrong when a very large repository is checked out in full, even on capable modern hardware.
Wasted Storage
Every file from every unrelated project sits on disk, consuming space for content a given engineer may never open even once.
Slower Indexing
Development tools that index the working directory for search, autocomplete, and navigation must process a vastly larger set of files than actually relevant.
Slower Status & Checkout
Operations that need to scan the working directory, like checking status, must examine every file present, even ones entirely irrelevant to current work.
Navigational Noise
Simply browsing the project’s file tree becomes harder when it’s dominated by dozens of unrelated services an engineer has no reason to interact with.
None of these problems are really about the repository’s history or its object database being too large in an absolute sense — Git’s object model, as covered elsewhere, already handles that efficiently through deduplication and compression. The problem is specifically the working directory: the literal, physical set of files sitting unpacked on disk, ready to be opened, indexed, and scanned.
4Architecture & Components
Sparse checkout’s mechanics rest on a small set of coordinated pieces within Git’s existing structure.
| Component | Role |
|---|---|
| Sparse-checkout file | A local configuration file listing which directories or path patterns should actually be populated in the working directory |
| Skip-worktree bit | An internal per-file flag in the index marking a file as tracked but deliberately excluded from the working directory |
| The index | Still references every tracked file in the repository, regardless of whether that file is actually materialized on disk |
| Cone mode | A simplified, directory-based matching mode for defining sparse-checkout patterns, covered in detail later |
The index — Git’s staging area — continues to reference every tracked file in the repository, whether or not that file is actually present in your working directory. Sparse checkout changes what’s physically written to disk, not what Git considers part of the tracked project as a whole.
5Internal Working
Here’s what actually happens internally when sparse checkout is configured and applied to a repository.
Sparse Checkout Is Enabled
The repository’s local configuration is updated to activate sparse-checkout behavior for future working-directory operations.
Desired Paths Are Specified
The user defines which directories should actually be included, either through cone-mode directory listings or more granular path patterns.
Git Marks Excluded Files in the Index
Every tracked file falling outside the specified paths has its skip-worktree bit set, marking it as tracked but intentionally not materialized.
The Working Directory Is Rewritten
Git removes files corresponding to excluded paths from the working directory (while their content remains safely in the object database) and ensures included paths are fully populated.
Subsequent Operations Respect the Sparse Pattern
Checkouts, branch switches, and pulls continue honoring the configured sparse pattern, only ever materializing the specified subset going forward.
6Data Flow & Lifecycle
flowchart TD
    A["Full repository history\nand object database"] --> B["Index tracks\nevery file"]
    B --> C{"File path matches\nsparse pattern?"}
    C -->|"Yes"| D["Skip-worktree bit unset\nFile materialized on disk"]
    C -->|"No"| E["Skip-worktree bit set\nFile stays in object DB only"]
    D --> F["Working directory:\nfocused, manageable subset"]
    E --> G["Available on demand if\nsparse pattern later changes"]
Fig 1 — Every file remains fully tracked; sparse checkout only decides what’s actually written to disk
The right-hand branch is worth dwelling on: excluded content isn’t deleted or inaccessible in any permanent sense. It remains fully present in Git’s object database, and updating the sparse-checkout pattern later to include a previously excluded path simply materializes it, pulling from data that was there the entire time.
7Cone Mode vs Non-Cone Mode
Advanced Concepts
Git offers two distinct ways to specify sparse-checkout patterns, with meaningfully different trade-offs in simplicity and performance.
| Aspect | Cone Mode (Recommended) | Non-Cone (Pattern) Mode |
|---|---|---|
| Pattern style | Whole directories, specified simply and predictably | Full gitignore-style pattern matching, including individual file patterns |
| Performance at scale | Optimized specifically for large repositories with deep directory trees | Can be significantly slower on very large repositories due to more complex matching |
| Flexibility | Somewhat less flexible — oriented around directory-level inclusion | More flexible, supporting fine-grained, individual file-level patterns |
| Recommended for | Most large monorepo use cases, especially at significant scale | Smaller repositories or genuinely fine-grained, file-specific needs |
Cone mode was introduced specifically in response to real-world performance problems observed with complex pattern matching on genuinely enormous repositories, and it’s now the generally recommended default for any large-scale sparse-checkout use case.
8Relationship to Partial Clone
Sparse checkout is frequently confused with, and often used alongside, a related but genuinely distinct feature: partial clone. Understanding the difference precisely is essential for using either one effectively.
Sparse Checkout: Controls the Working Directory
Determines which tracked files are actually materialized as files on disk, after the full repository history and object data have already been fetched.
Partial Clone: Controls What’s Actually Fetched
Determines which object data (particularly large file blobs) is downloaded from the remote at all during clone and fetch operations, potentially deferring or entirely avoiding fetching content for objects outside your area of interest.
On a genuinely enormous repository, sparse checkout alone still requires a full clone’s worth of network transfer and local storage for the object database, even though only a fraction ends up in the working directory. Combining it with partial clone lets an organization also avoid downloading object data for content that will never even be checked out, addressing both the working-directory problem and the initial clone-size problem together.
9Advantages, Disadvantages & Trade-offs
Advantages
- Dramatically reduces working-directory size and file count for engineers working in a small corner of a large repository
- Improves editor, IDE, and Git command performance by shrinking what needs to be scanned or indexed
- Preserves the benefits of a single, unified repository without fragmenting it into separate projects
- Excluded content remains fully available and can be brought in later without re-cloning anything
Trade-offs
- Doesn’t, by itself, reduce what’s fetched or stored — that requires pairing it with partial clone for full benefit
- Adds a layer of configuration complexity most small or medium repositories simply don’t need
- Switching which paths are included requires an explicit reconfiguration step, not something that happens automatically as work shifts
- Tooling and scripts that assume the entire repository is always present on disk may behave unexpectedly against a sparse working directory
10Reliability Considerations
Because sparse checkout changes a fundamental assumption many tools make — that the working directory mirrors the full repository — a few reliability factors are worth understanding clearly.
- Excluded files are genuinely absent from the working directory, not just hidden. Scripts or build processes that directly reference a path outside the sparse pattern will fail to find it, since it simply isn’t materialized on disk.
- Switching branches still works correctly within the sparse scope. Git continues applying the configured sparse pattern consistently across branch switches, so the working directory’s focused subset remains stable as you move between branches.
- Committing changes still works normally for included paths. Sparse checkout affects what’s visible and editable, not the correctness of Git’s core commit and history mechanics for the content you do have.
- Misconfigured patterns can silently exclude something genuinely needed. A too-narrow sparse-checkout pattern can leave a developer confused about why an expected file simply doesn’t exist locally, when in fact it’s just excluded from materialization.
11Performance & Scalability
Sparse checkout’s core value proposition is fundamentally about performance and scalability, and it’s worth being precise about exactly where those gains come from.
- Filesystem-level operations scale with what’s actually on disk. Anything that walks the working directory — status checks, file watchers, build tool scans — directly benefits from there simply being far fewer files present to examine.
- Editor and IDE indexing time drops substantially. Tools that build a searchable index of the project only need to process the materialized subset, not the repository’s entire, potentially enormous file count.
- Cone mode specifically addresses pattern-matching overhead at scale. On repositories with extremely deep or complex directory structures, cone mode’s simplified matching avoids performance costs that non-cone pattern matching can incur.
- Real gains compound when paired with partial clone. Addressing both what’s fetched and what’s materialized together produces the most substantial improvement for genuinely massive repositories, rather than addressing either concern in isolation.
12Team Workflow Implications
Adopting sparse checkout across a team or organization has practical implications beyond any individual engineer’s own setup, worth planning for deliberately.
Onboarding Complexity
New team members need clear guidance on which sparse-checkout pattern matches their actual area of work, adding a setup step beyond a simple, uniform clone instruction.
Cross-Team Collaboration Patterns
An engineer who temporarily needs to work across service boundaries — debugging an integration issue spanning two areas, for instance — needs a straightforward way to expand their sparse pattern temporarily and contract it again afterward.
Standardized Sparse Patterns per Team
Larger organizations sometimes maintain and share predefined sparse-checkout configurations aligned with team boundaries, reducing the burden on individual engineers to figure out the right pattern themselves.
13Design Patterns & Anti-patterns
Pattern
Default to cone mode for any sparse-checkout configuration on a genuinely large monorepo.
Why It Works
It provides the performance characteristics specifically designed for scale, avoiding the pattern-matching overhead that non-cone mode can introduce on very large, deep directory structures.
Pattern
Pair sparse checkout with partial clone for repositories where the initial clone itself, not just the working directory, is a genuine pain point.
Why It Works
It addresses both halves of the scalability problem together — what’s fetched and what’s materialized — rather than leaving a large, slow initial clone as an unaddressed bottleneck.
Anti-pattern
Assuming sparse checkout reduces network transfer or local storage on its own.
Why It’s Risky
Without partial clone, the full object database is still fetched and stored regardless of the sparse-checkout configuration — teams expecting bandwidth or disk savings from sparse checkout alone will be genuinely surprised when those numbers don’t move.
Anti-pattern
Configuring an overly narrow sparse pattern without accounting for shared libraries or common dependencies that other included code actually relies on.
Why It’s Risky
Builds or tests can fail mysteriously when a genuinely necessary shared dependency simply isn’t present on disk, and the resulting error often doesn’t clearly point back to a sparse-checkout misconfiguration as the root cause.
14Best Practices & Common Mistakes
large repositories
team’s folder
and storage gains
- Use cone mode by default for large-scale sparse-checkout configurations. It’s specifically designed for the performance characteristics large monorepos need.
- Account for shared dependencies when defining a sparse pattern. Include not just your team’s own directories, but any common libraries or configuration your code genuinely depends on.
- Pair with partial clone when initial clone time or size is itself a problem. Sparse checkout alone doesn’t reduce what’s fetched — only what’s materialized afterward.
- Document standard sparse patterns for each team or service boundary. This removes the guesswork for new engineers trying to figure out the right configuration for their actual work.
- Communicate clearly when a script or tool assumes a full working directory. Flag any internal tooling that might break under a sparse configuration, so teams can address it deliberately rather than discovering it through confusing failures.
15Real-World Usage Patterns
Company-Wide Monorepos
Organizations maintaining a single enormous repository across many teams and services rely heavily on sparse checkout to keep individual engineers’ working directories manageable despite the repository’s overall scale.
Focused Access to Shared Tooling
Engineers working specifically on shared build tooling or infrastructure code within a larger monorepo often configure sparse checkout to include just that tooling plus the specific service they’re actively validating it against.
Faster, Targeted Automated Checkouts
Some automated pipelines use sparse checkout to speed up their own checkout step, materializing only the specific paths relevant to the particular build or test job actually being run.
Temporary Pattern Expansion
An engineer investigating an issue spanning multiple services can temporarily broaden their sparse-checkout pattern to include the additional code needed, then narrow it back afterward.
16Frequently Asked Questions
17Summary and Key Takeaways
Key Takeaways
- Sparse checkout is a core Git feature that lets you materialize only a chosen subset of a repository’s tracked files into your working directory, while Git still fully tracks the entire repository underneath.
- It exists specifically to keep enormous, shared monorepos practical to work in day to day, without forcing organizations to fragment a unified codebase into many separate repositories.
- Excluded content isn’t deleted — it remains fully present in the object database and can be materialized later simply by adjusting the sparse pattern.
- Cone mode is the generally recommended approach for large-scale use, offering better performance than more granular, non-cone pattern matching.
- Sparse checkout is often confused with partial clone; the two are complementary but distinct — one controls the working directory, the other controls what’s actually fetched from the remote.
- Real-world adoption requires deliberate planning around shared dependencies, onboarding, and any internal tooling that assumes a full working directory is always present.
- Used well, especially paired with partial clone, sparse checkout lets even the largest monorepos remain genuinely comfortable for individual engineers to work in, without sacrificing the coordination benefits of a single, unified repository.